The "Heavy" Cache Pattern: Smart Memory Management for Expensive Resources
A single-item cache with TTL eviction can transform your application's performance while keeping memory usage in check.
How a single-item cache with TTL eviction can transform your application’s performance while keeping memory predictable on resource-constrained hardware
The heavy cache is a kind of cache that can hold at most one item in it.
Introduction
When building applications that load expensive resources — machine learning models or API clients — on limited hardware, you face a classic engineering trade-off: speed vs. memory. Load everything upfront and you exhaust memory. Load on-demand and you sacrifice latency.
What if you could have both?
In this article, I’ll walk you through a caching pattern we call the “Heavy” Cache — an in-memory cache limited to just one item with automatic TTL-based eviction. It sounds counterintuitive, but this constraint is precisely what makes it powerful for development environments and multi-purpose hardware.
The Problem: Expensive Resources on Limited Hardware
Consider these real-world scenarios when working on a single development machine or cost-constrained environment:
- Image Generation Models: Takes 15+ seconds to load (Stable Diffusion on Mac Mini M1), consumes several gigabytes of VRAM or unified memory
- LLM Models Running Locally: Tools like LlamaCpp enable running large language models locally, requiring substantial memory allocation
- Machine Learning Inference: Various ML models for computer vision, natural language processing, and other tasks demand significant computational resources
When working on shared or limited hardware (like a Mac Mini M1 used for multiple purposes), you don’t want to:
- Reload these resources on every request (too slow)
- Keep unlimited instances cached (memory explosion)
- Manually manage lifecycle (error-prone)
Note on Production Deployments: In production environments, the typical approach is to use dedicated hardware per AI model to ensure consistent performance and availability. The Heavy Cache pattern is designed for development, prototyping, and scenarios where multiple models must share the same hardware resources.
Generative AI and Resource Management
Generative AI models have become increasingly important in modern applications. Whether you’re generating images with Stable Diffusion or other locally-run image generation models, or running large language models locally with tools like LlamaCpp, these systems demand careful memory management. The Heavy Cache pattern is particularly valuable for generative AI workloads on limited hardware, where model initialization is expensive but amortization across multiple requests can dramatically improve user experience during development and testing.
The Solution: Heavy Cache with Limit=1
Here’s how we register the cache in our application:
from p6_cache import CacheManager, InMemoryCacheBackend, NoOpCacheBackend, EvictionPolicy
cache_manager = CacheManager()
heavy_backend = InMemoryCacheBackend(
    max_items=1,                        # Only ONE item at a time
    eviction_policy=EvictionPolicy.TTL,
    default_ttl=60                      # 60 seconds of inactivity
)
noop_backend = NoOpCacheBackend()       # Bypass cache when needed
cache_manager.register_backend("heavy", heavy_backend)
cache_manager.register_backend("noop", noop_backend)
context.register_manager(cache_manager)
Why limit=1? This isn’t a limitation — it’s a safety mechanism designed for single-hardware constraints:
- Prevents unbounded memory growth on limited resources
- Forces conscious design decisions
- Creates predictable memory footprint
- Reflects the reality that most development machines can only hold one large model in GPU/memory at a time
How It Works: The Technical Details
Context Manager Pattern
The cache uses Python’s context manager for elegant resource handling:
cache_manager = CacheManager.from_context(context)
backend = cache_manager.backend("heavy")
async with backend.get("model_key", fetch_method, cleanup=cleanup_fn) as resource:
    # Use the resource
    result = await resource.process(data)
# Automatically tracked for eviction
What happens under the hood:
- On Entry: Check cache → if miss, compute and store → increment active context counter
- During Use: Resource stays in memory, protected from eviction
- On Exit: Decrement counter → if TTL expired and no active contexts → cleanup runs
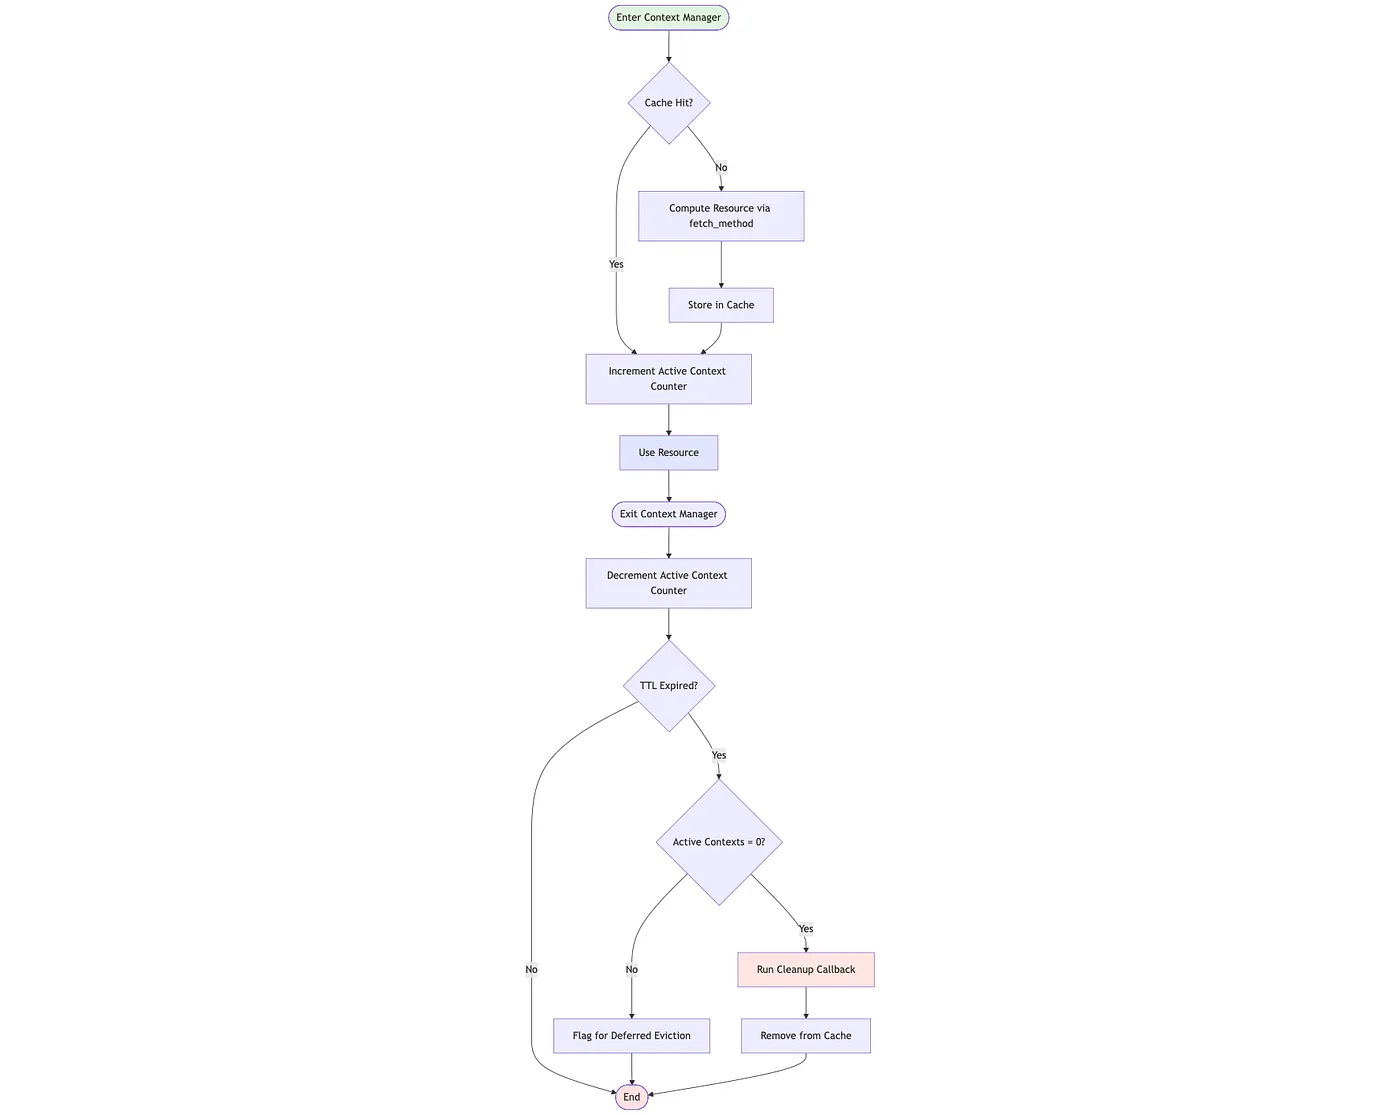
Illustration made using mermaidjs
Eviction Policies
The backend supports four eviction strategies:
- TTL: Expired items first, then LRU fallback, for time-sensitive resources
- LRU: Least recently accessed
- LFU: Least frequently accessed
- FIFO: Oldest created first, for queue-like behavior
Thread Safety: The Hard Part
Multi-threaded access requires careful coordination:
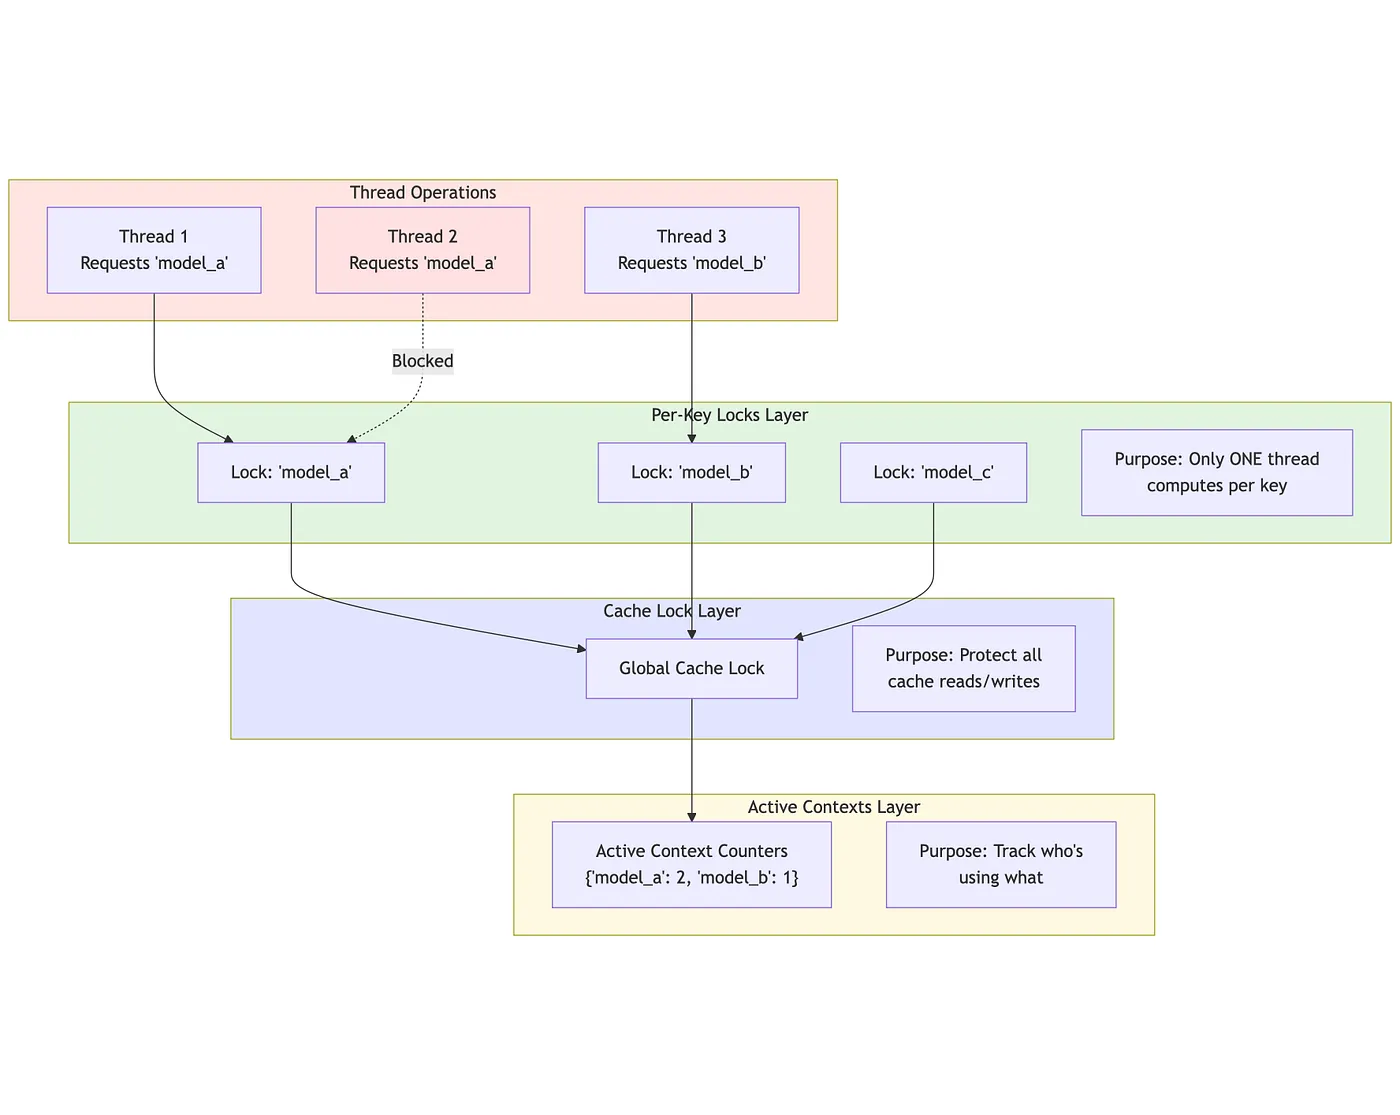
Illustration made using mermaidjs
Key invariants maintained:
- Only one thread computes a value for a given key simultaneously
- No eviction occurs while a context is active (deferred eviction)
- Cache dictionary is always consistent
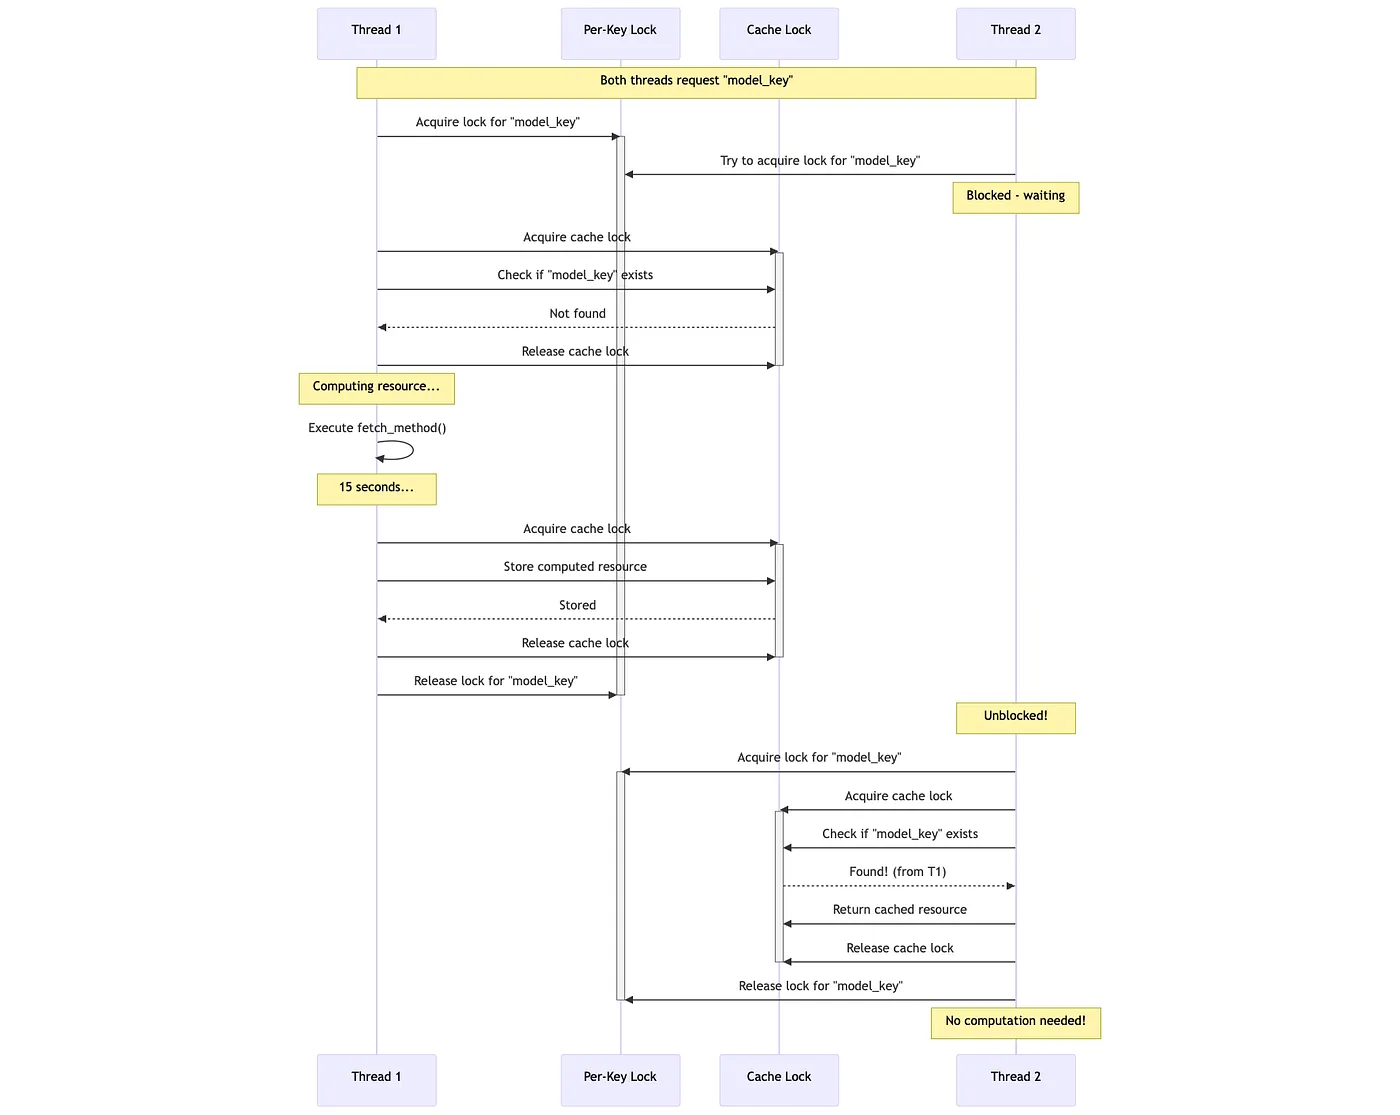
Illustration made using mermaidjs
Automatic Garbage Collection
For TTL-based caches, a background thread handles cleanup:
def _gc_loop(self):
    while not self._gc_shutdown.wait(check_interval):
        with self.cache_lock:
            # Find expired items with no active contexts
            expired = [k for k, v in self.cache.items()
                      if v.is_expired() and self.active_contexts.get(k, 0) == 0]
            for key in expired:
                self._invoke_cleanup(self.cache[key])
                del self.cache[key]
Important detail: TTL is measured from last_accessed, not created_at. Actively used items never expire!
Real-World Usage: ML Model Loading
Here’s how we cache image generation models:
async def load_image_generation_model(context: Context, model_id: str):
    cache_manager = CacheManager.from_context(context)
    backend = cache_manager.backend("heavy")

    async def fetch_method():
        # Show progress to user while loading
        async with context.add_tqdm_progression(f"Loading {model_id}"):
            pipe = StableDiffusionPipeline.from_pretrained(
                model_id,
                torch_dtype=torch.float16
            )
            pipe = pipe.to("mps")  # GPU
            return pipe

    def cleanup(pipe):
        # Critical: Free GPU memory!
        print(f"Releasing model {model_id}")
        torch.mps.empty_cache()
        gc.collect()

    async with backend.get(f"model_{model_id}", fetch_method, cleanup=cleanup) as pipe:
        image = pipe(prompt=prompt).images[0]
        return image
Why this works perfectly with limit=1 on single hardware:
- Single GPU/unified memory can only hold one large model at a time
- 60-second TTL keeps model warm between user requests during development
- Cleanup callback ensures GPU memory is freed for the next model
- Next request within 60s = instant generation
- Enables multi-purpose use of the same hardware
The NoOpCacheBackend: Strategic Bypass
Sometimes you need to bypass caching entirely:
noop_backend = NoOpCacheBackend()
cache_manager.register_backend("noop", noop_backend)
Key differences from InMemoryCacheBackend:
- does not store values,
- does not use locks,
- cleanup on context exit,
When to use NoOp:
- Testing: Verify cleanup logic runs correctly without cache interference
- Dynamic bypass: Disable caching via configuration
- Interface compatibility: Same API, different behavior
def get_backend(cache_disabled: bool) -> CacheBackend:
    """Return appropriate backend based on configuration."""
    if cache_disabled:
        return cache_manager.backend("noop")
    return cache_manager.backend("heavy")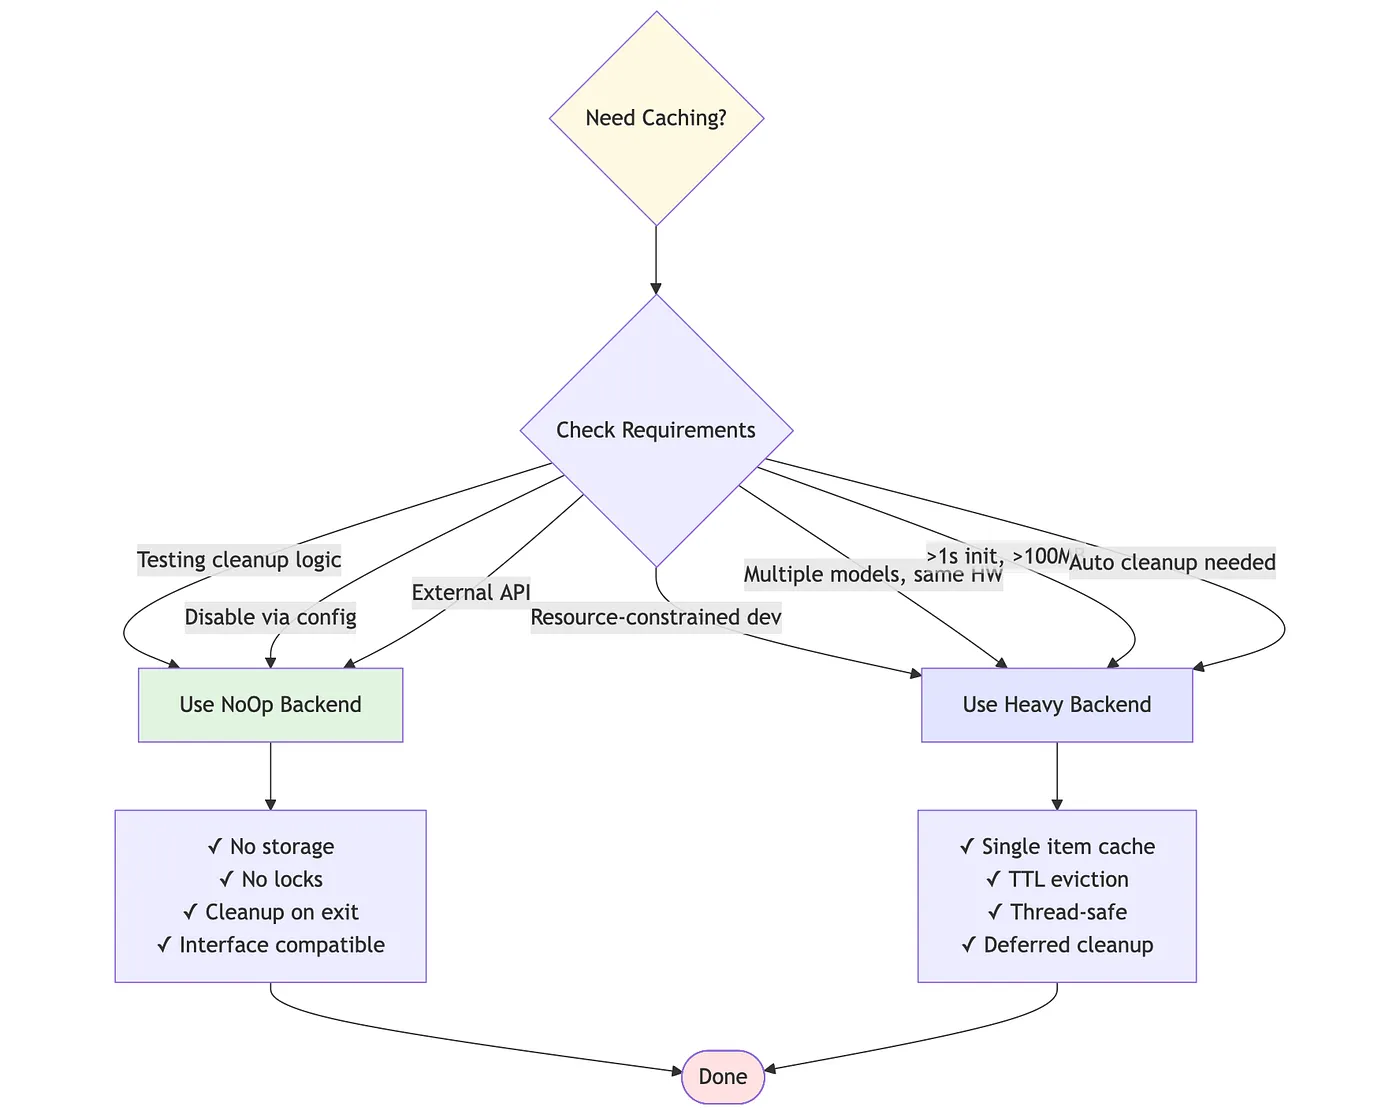
Illustration made with mermaidjs
The CacheManager: Registry Pattern
The CacheManager ties everything together:
class CacheManager(AbstractManager):
    def register_backend(self, name: str, backend: CacheBackend) -> None:
        self._backends[name] = backend

    def backend(self, name: str) -> CacheBackend:
        return self._backends[name]

    def on_unregister(self) -> None:
        # Graceful shutdown of all backends
        for backend in self._backends.values():
            backend.shutdown()
Benefits:
- Named backends for different use cases (“heavy”, “noop”, “redis”, etc.)
- Dependency injection via context
- Automatic cleanup on application shutdown
Use Heavy Cache (limit=1) when:
- Working on resource-constrained hardware (development machines, Mac Mini, etc.)
- Need to support multiple AI models on the same hardware
- Resource takes >1 second to initialise
- Memory footprint is substantial (>100MB)
- Same resource is reused across multiple requests
- You want automatic cleanup on inactivity
- Prototyping or developing locally before deploying to dedicated infrastructure
Don’t use when:
- Deploying to production with dedicated hardware per model (use standard deployment patterns instead)
- Resource is lightweight (<10MB)
- Each request needs a fresh instance
- Freshness is more important than speed
- You need to cache multiple different items simultaneously
- You have sufficient hardware resources to keep all models loaded
Production Deployment Considerations:
For production environments, consider:
- Dedicated hardware/containers per AI model for consistent performance
- Horizontal scaling with load balancers
- Model-specific optimisation and resource allocation
- The Heavy Cache pattern is designed for development and resource-constrained scenarios, not as a production scaling solution