Python Pandas library: the tricks behind DataFrame filtering
Spoiler alert, it is mostly about operator overloading and predicates!
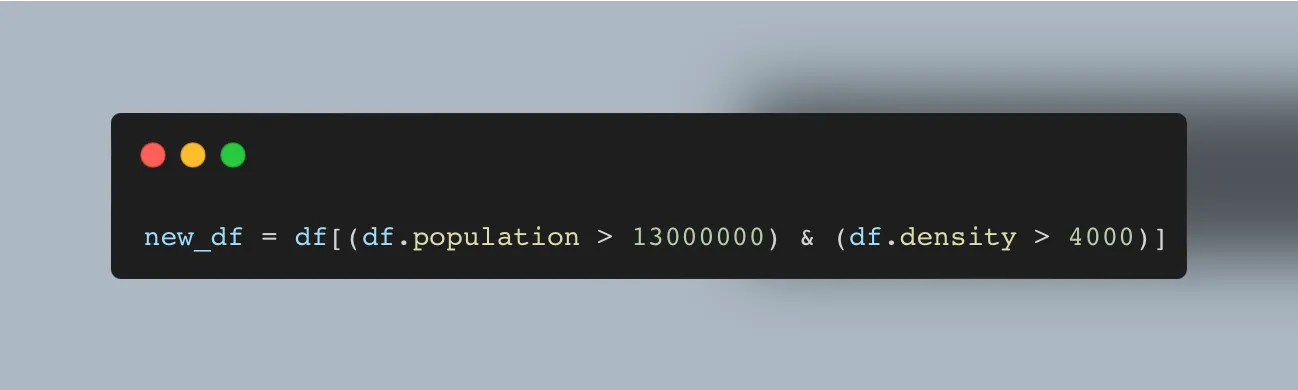
One of the available syntax to filter a DataFrame, but how does it works? Illustration by the author.
Spoiler alert, it is mostly about operator overloading and predicates!
This article isn’t intended for Pandas expert. It will not tell you exactly how it does really works, but will first give you access to the principles involved so that they become more accessible. It will then show you an equivalent implementation so that you can draw inspiration from it.
The three principles behind this the DataFrame filtering syntax
1) DataFrame filtering use operator overloading
When we write new_df = df[(df.population … 4000)] we are not:
- accessing an array’s item by it’s index
- accessing a slice of an array using a range
- accessing a value in a dict by it’s key
What we are doing is calling the dataframe instance __getitem__(self, key) subscript operator overloading method.
Overloading this method allows to do much more than the classical usage for list and dict. In the case of DataFrame, it allow to have access to a new DataFrame when the given key represents filters.
2) DataFrame properties are not “real” values
When we write df.population or df.density in our example , we are not accessing directly the content of a row or the content of a column, we are retrieving the way to work with the content of a column.
In the case of DataFrame filtering you can consider* that df.population is equivalent to a class with a method taking a row as parameter and returning the population value for the given row.
(*As a matter of fact, pandas use a structure that is column oriented more than row oriented, that is to say you can consider df.population as a list of index-value pairs)
3) DataFrame filtering use predicates
In programming, a predicate is a function that take one parameter and returns either True or False.
What happens when we write df.population > 13000000?
- we get an instance of the object that will allow us to work with the content of the population column,
- then the __gt__(self, obj) method of this object is called (the one responsible for overloading the > operator) and it will give us a predicate that will return True if the population value for a given row is strictly superior to 13 million and False otherwise
The same things is made for df.density > 4000
As for the & in the middle of (df.population > 13000000) & (df.density > 4000) it will allow to have access to a combining logical “and” predicate between the first (population based) and the second (density based) one. We can’t use directly the logical “and” keyword as no operator overloading is available for it, so the bitwise and operator __and__(self, obj) is used instead.
Lets write a simple examples using the same principles
The source code behind Pandas is, of course, more complex than the one I will propose you, as it must handle more use cases and contains securities.
We will consider a list of dictionaries as our input data and will only write a source code corresponding to what we need for our famous new_df = df[(df.population … 4000)] use case.
Code for the predicates
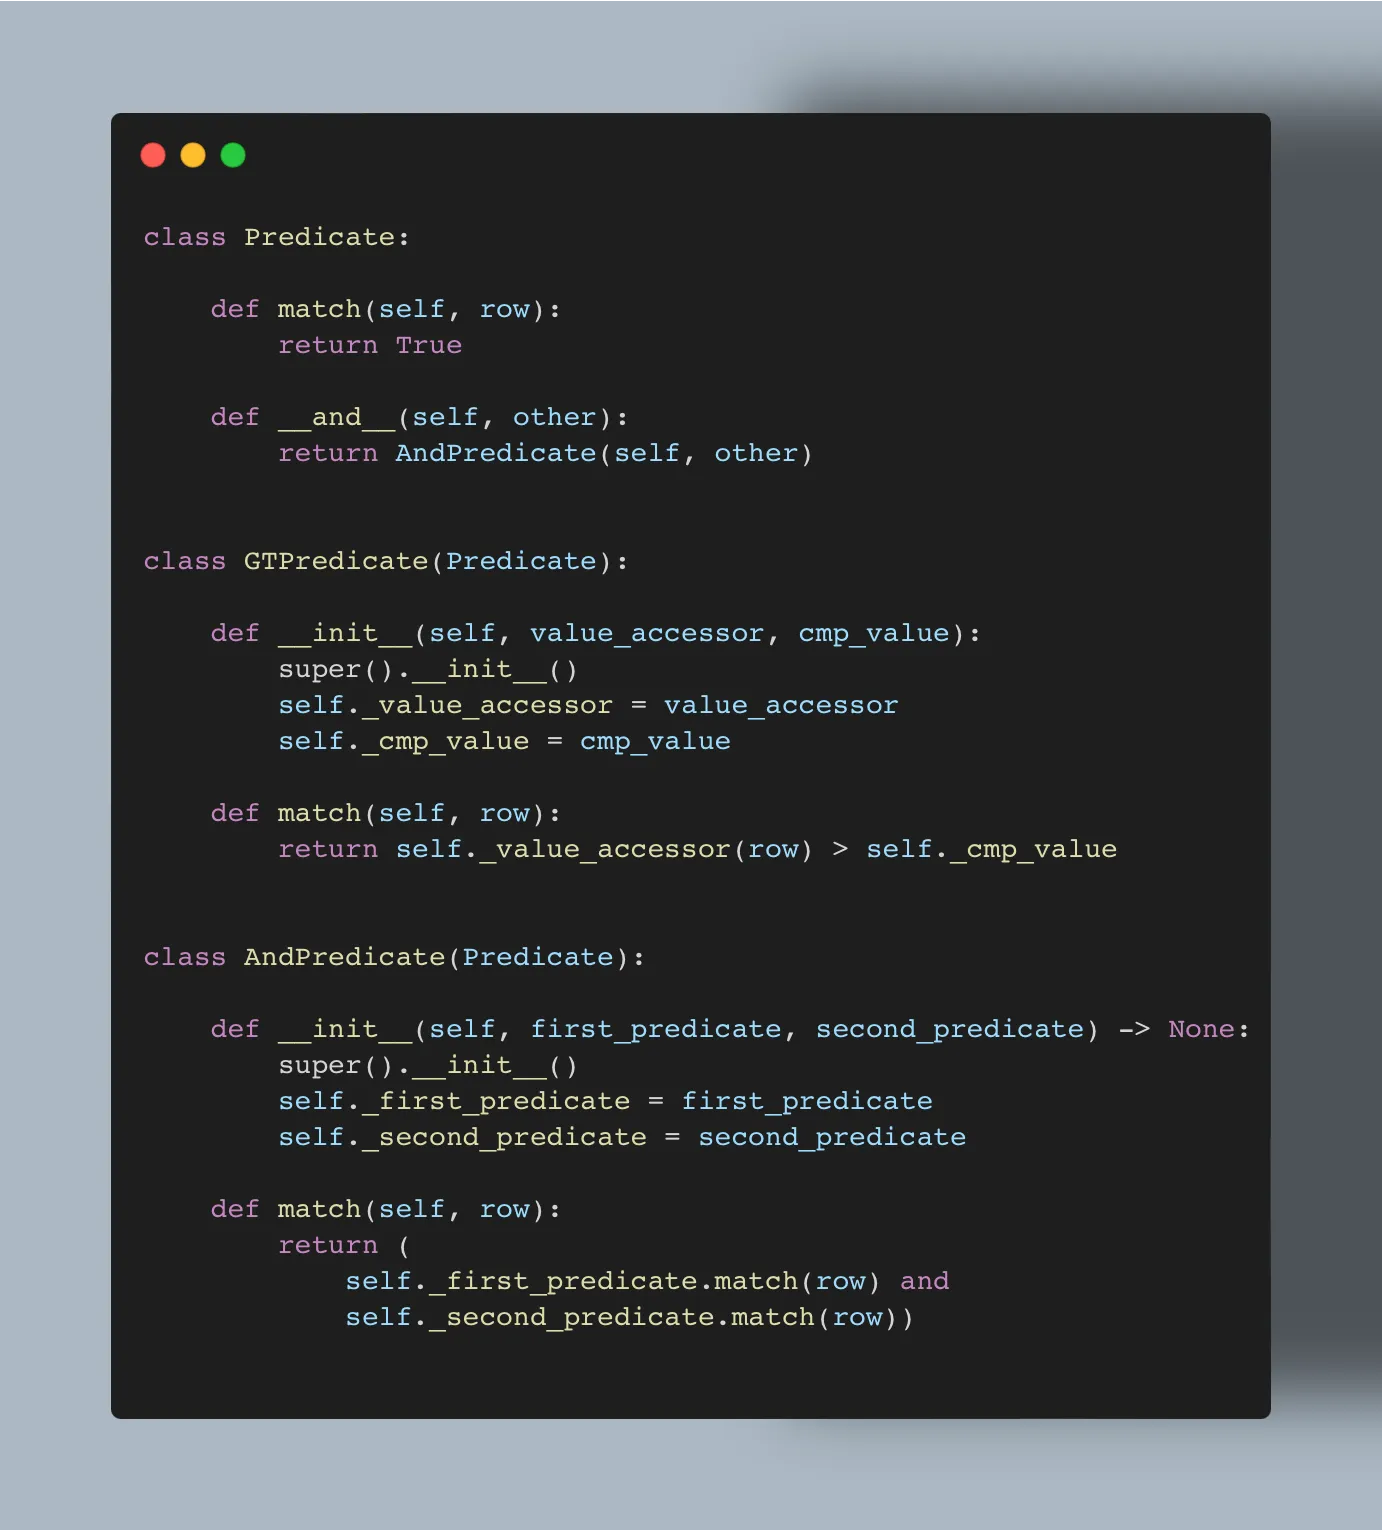
Illustration by the author.
- Predicate, it has a match method always returning True, and it overrides the & operator to return a AndPredicate,
- GTPredicate, it uses both a value_accessor and a value to compare with. It will match when the value retrieved for a given row is greater than (gt) the given value
- AndPredicate, it uses two predicate. It will match when both sub-predicates matches.
Value accessor
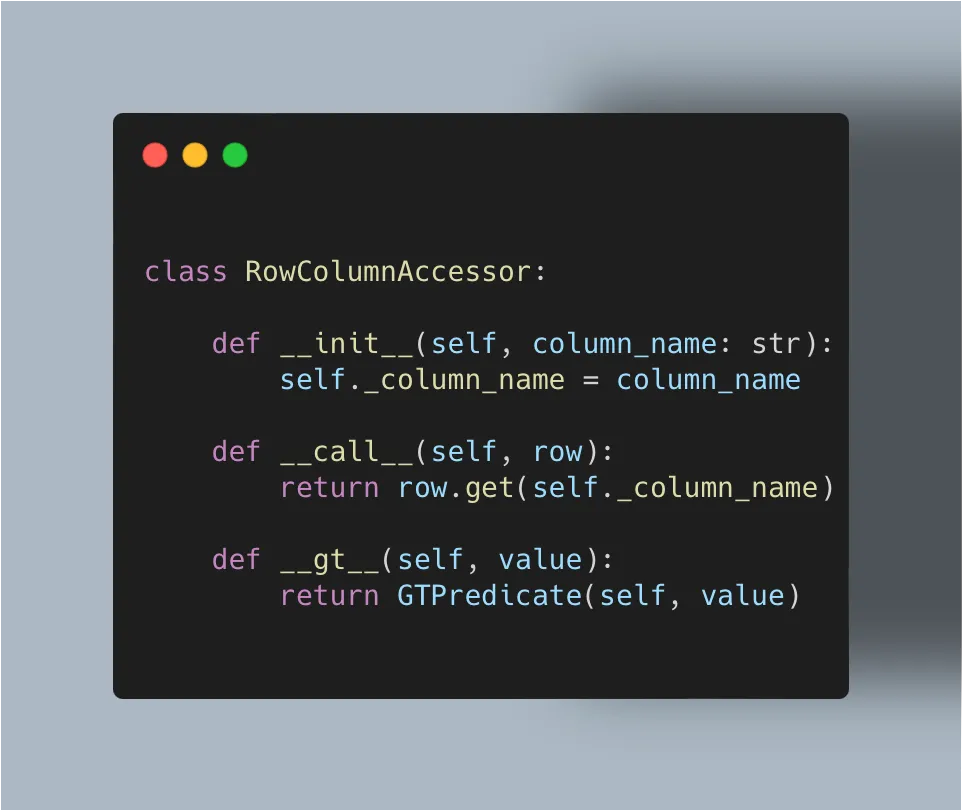
Illustration by the author.
We will define a RowColumnAccessor, it takes a column_name, that is to say the name of key in a dictionary.
It will be used to retrieve the value associated with the given key for a row (__call__ method)
It overrides the > operator to return a GTPredicate (greater than predicate)
The DataContainer
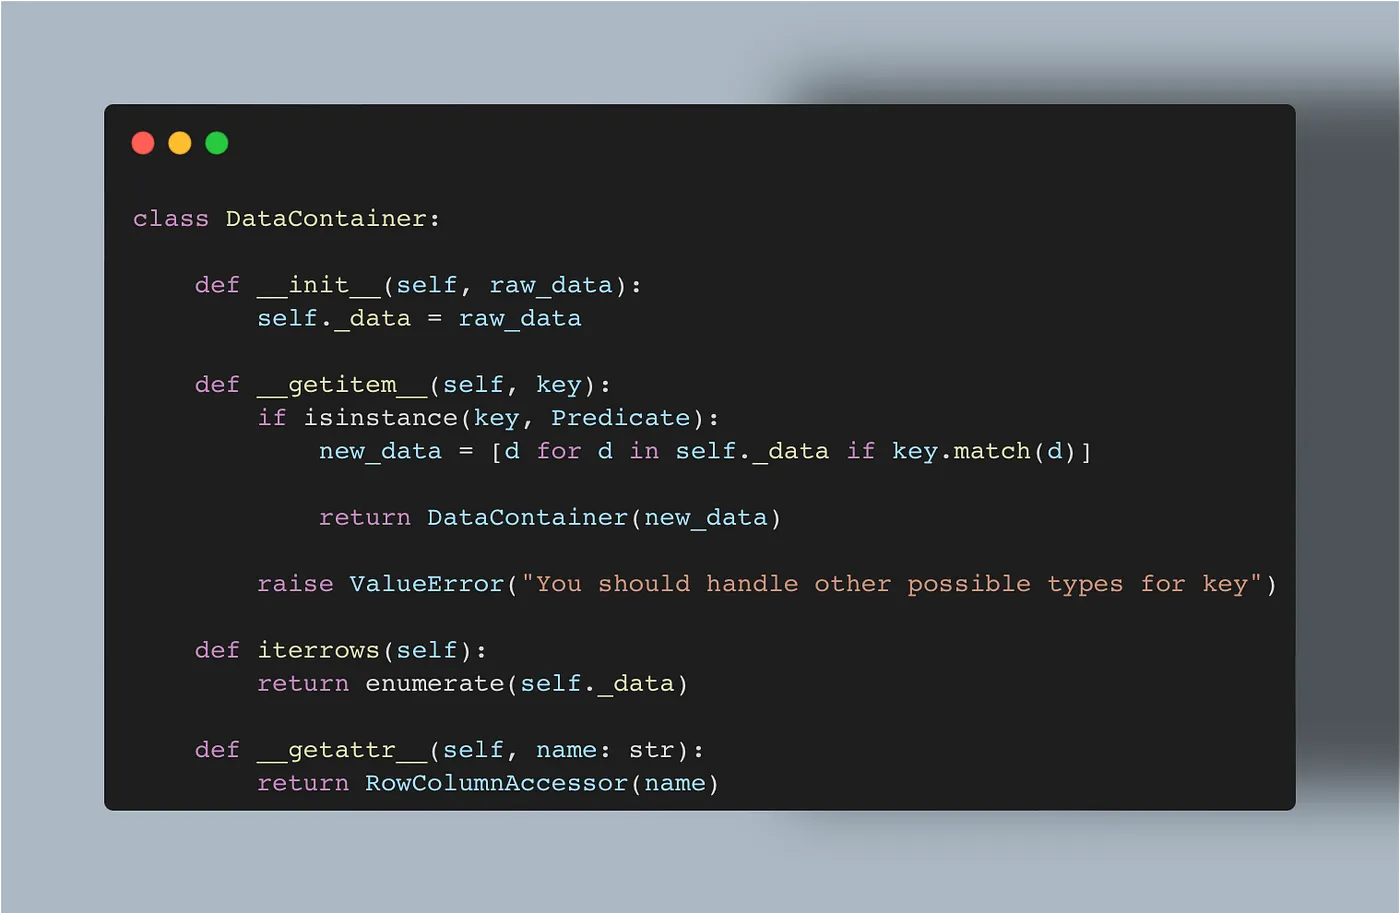
Illustration by the author.
The DataContainer store the raw_data (the list of dictionaries).
It define __getitem__ to override the [] operator. You can see there that it will work only with a Predicate instance. It will use it to construct a new, with filtered data, DataContainer.
It also define the __getattr__ method, to create RowColumnAccessor instances, and an iterrows method to enumerate the content.
Testing it
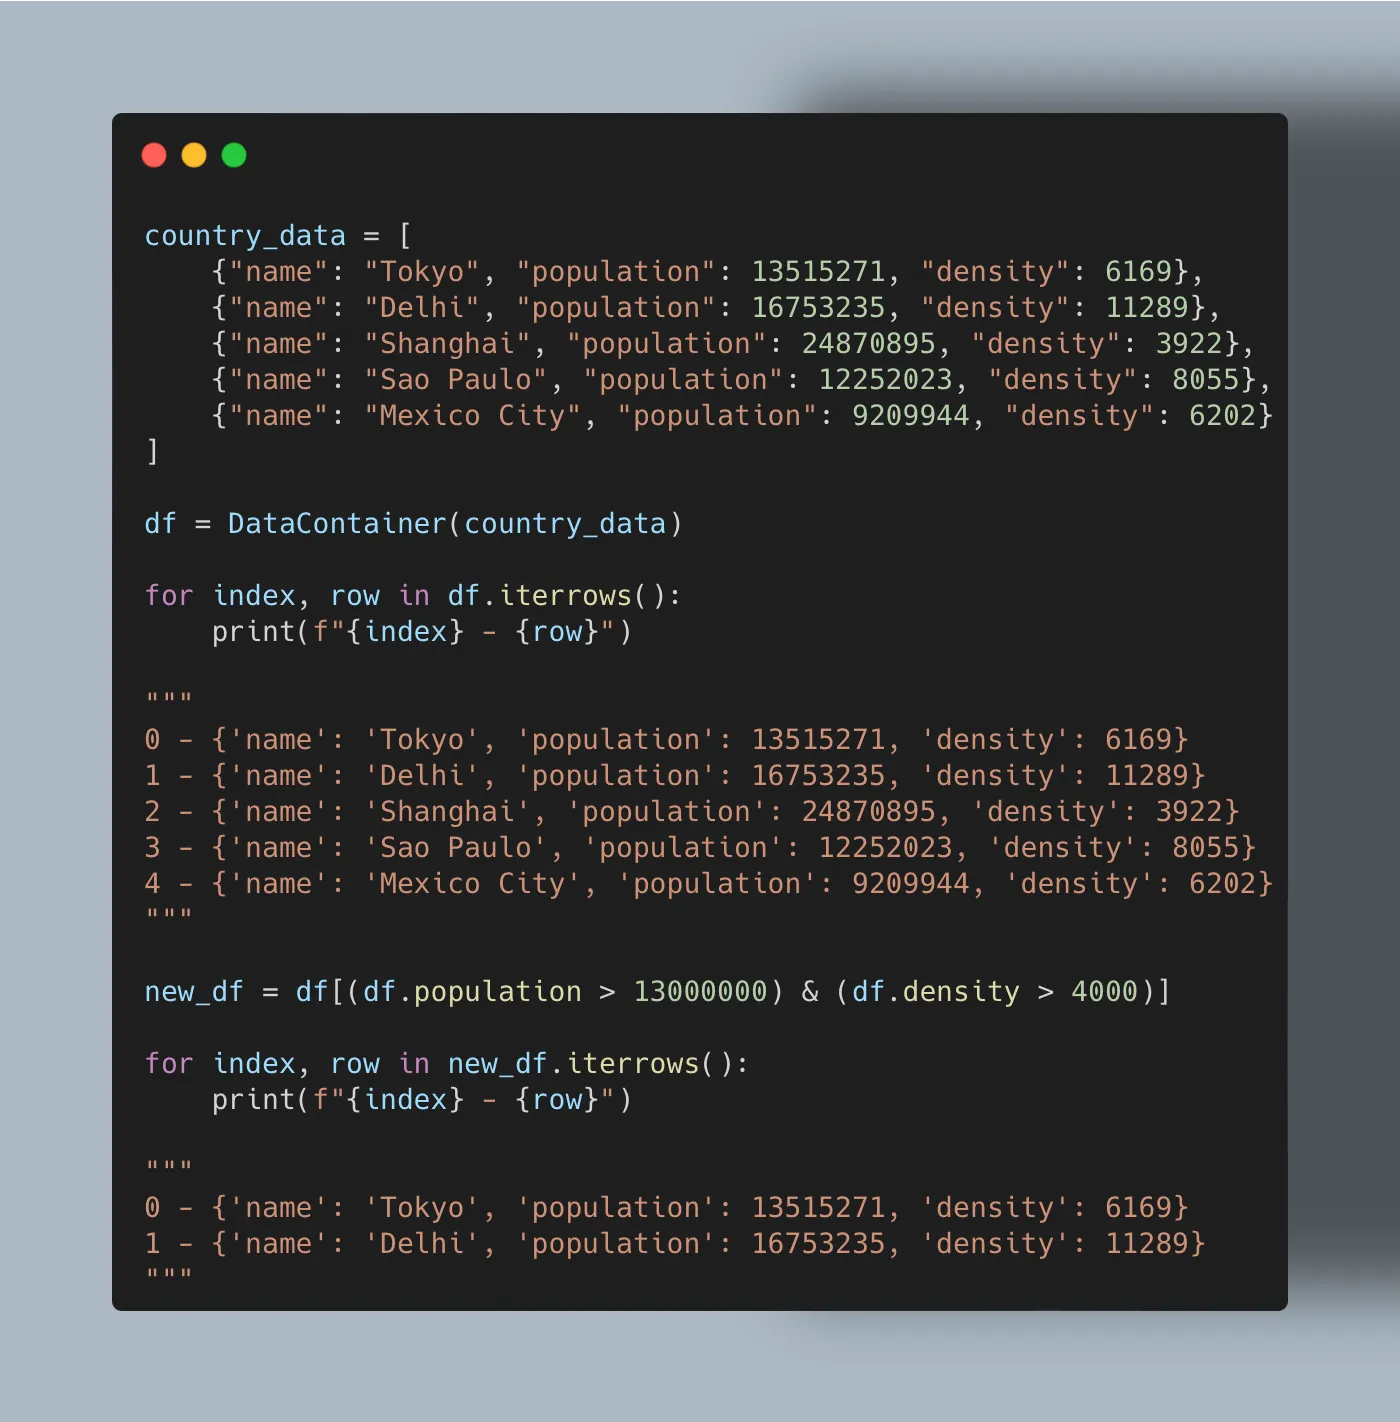
Testing what we wrote so far, illustration by the author
- We start by constructing the source_data, here it is a list with data about 5 cities.
- We print the DataContainer content using iterrows.
- We then filter cities using the population and the density.
- If 3 cities from our dataset have a population greater than 13 million, only Tokyo and Delhi also match the density criteria.
Full source code is accessible below:
# values from https://en.wikipedia.org/wiki/List_of_largest_cities

country_data = [
    {"name": "Tokyo", "population": 13515271, "density": 6169},
    {"name": "Delhi", "population": 16753235, "density": 11289},
    {"name": "Shanghai", "population": 24870895, "density": 3922},
    {"name": "Sao Paulo", "population": 12252023, "density": 8055},
    {"name": "Mexico City", "population": 9209944, "density": 6202}
]


class Predicate:

    def match(self, row):
        return True

    def __and__(self, other):
        return AndPredicate(self, other)


class GTPredicate(Predicate):

    def __init__(self, value_accessor, cmp_value):
        super().__init__()
        self._value_accessor = value_accessor
        self._cmp_value = cmp_value

    def match(self, row):
        return self._value_accessor(row) > self._cmp_value


class AndPredicate(Predicate):

    def __init__(self, first_predicate, second_predicate) -> None:
        super().__init__()
        self._first_predicate = first_predicate
        self._second_predicate = second_predicate

    def match(self, row):
        return (
            self._first_predicate.match(row) and
            self._second_predicate.match(row))


class RowColumnAccessor:

    def __init__(self, column_name: str):
        self._column_name = column_name

    def __call__(self, row):
        return row.get(self._column_name)

    def __gt__(self, value):
        return GTPredicate(self, value)


class DataContainer:

    def __init__(self, raw_data):
        self._data = raw_data

    def __getitem__(self, key):
        if isinstance(key, Predicate):
            new_data = [d for d in self._data if key.match(d)]

            print(new_data)

            return DataContainer(new_data)

        raise ValueError("You should handle other possible types for key")

    def iterrows(self):
        return enumerate(self._data)

    def __getattr__(self, name: str):
        return RowColumnAccessor(name)


df = DataContainer(country_data)

for index, row in df.iterrows():
    print(f"{index} - {row}")

"""
0 - {'name': 'Tokyo', 'population': 13515271, 'density': 6169}
1 - {'name': 'Delhi', 'population': 16753235, 'density': 11289}
2 - {'name': 'Shanghai', 'population': 24870895, 'density': 3922}
3 - {'name': 'Sao Paulo', 'population': 12252023, 'density': 8055}
4 - {'name': 'Mexico City', 'population': 9209944, 'density': 6202}
"""

new_df = df[(df.population > 13000000) & (df.density > 4000)]

for index, row in new_df.iterrows():
    print(f"{index} - {row}")

"""
0 - {'name': 'Tokyo', 'population': 13515271, 'density': 6169}
1 - {'name': 'Delhi', 'population': 16753235, 'density': 11289}
"""
That’s all folks!
I hope you will have learn one trick or two with this.
You can also read more about operator overloading with my previous article about them.
https://medium.com/@jerome.o.diaz/python-cheatsheet-operator-overloading-247bfce6a16f